Anthropic's Fable 5.2 Completes 41% of Real Freelance Jobs on Remote Labor Index
The score nearly doubles the next-best system on a benchmark built from paid Upwork projects, though the model still fails most of the work it is given.
By Nakoda News Desk
·2 min read
Prefer Nakoda News on Google
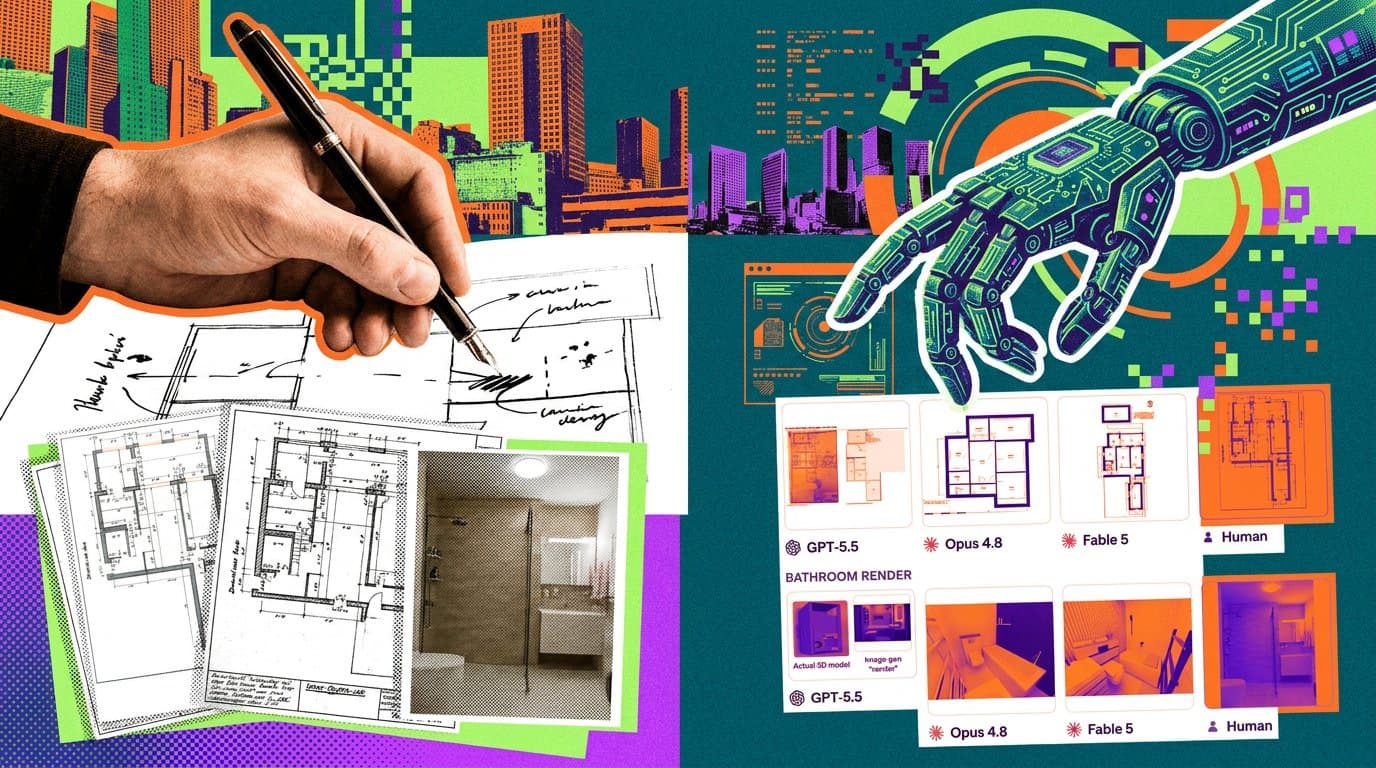
Anthropic's Claude Fable 5.2 completed 41.3 percent of the projects in the Remote Labor Index, a benchmark made up of real freelance commissions, according to the public leaderboard run by Scale Labs. That is almost double the next-best system's score, and more than 16 times the 2.5 percent managed by the top agent, Manus, when the index launched about a year ago.
The Remote Labor Index, built by Scale Labs and the Center for AI Safety (CAIS), does not test isolated skills. It gives AI agents complete jobs that freelancers on Upwork had already been paid to deliver, and counts a project as done only if a paying client would accept the result. That makes it one of the more direct measures of how much commissioned digital work an agent can take over. The gain over the past four months is far steeper than anything before it.
In July, Anthropic's earlier Fable 5 led the index at about 16 percent. Fable 5.1, the new model's direct predecessor, now scores 17.92 percent. Behind Fable 5.2 on the current leaderboard are Anthropic's Opus 5.5 at 21.25 percent, OpenAI's GPT 6 Astra at 20.83 percent and Google's Gemini Argon 4 at 17.08 percent. Older models such as GPT-5.2 and Gemini 3 Pro score below 3 percent. Scale Labs publishes the scores without confidence intervals.
Anthropic released Fable 5.2 this week alongside Mythos 5.2. The result arrives as the company markets its shares to investors ahead of a Nasdaq listing planned for later this month.
Where the Gains Came
Scale Labs said on X that the biggest improvements were in editing audio and music, designing architecture and interior spaces, and building 3D models, The Decoder reported. The model also completed long, complex projects that earlier leaders regularly failed. Nearly 50 of its successful completions were jobs no agent in the test had solved before.
Scale Labs said the model can still barely handle some categories, especially industrial product design and animation. When agents fail, the researchers said, they typically hand in amateur-quality work, incomplete results, broken files or contradictory designs. Even at 41.3 percent, Fable 5.2 failed most of the jobs it attempted.
How the Jobs Are Graded
The dataset contains 240 completed projects from 358 verified Upwork professionals, worth about $144,000 in total. The average project cost $632.60 and took a human freelancer just under 29 hours. The work ranges from video editing and CAD design to game development and data analysis. Agents work in a virtual workspace with professional software such as Blender, GIMP and Audacity, plus AI tools for generating images, audio and video.
Trained human experts grade each submission. They open the files in the relevant software and compare them with what the human freelancer delivered. CAIS has tried to automate this step with AI graders but has not yet succeeded. The AI reviewers struggle to operate the professional software themselves, so submissions that look polished but are technically flawed fool them, and they rate models far too generously. Until that changes, every new entry on the leaderboard depends on people checking the work by hand.
Sources
- Scale Labs · Remote Labor Index leaderboard
Produced with AI assistance from the sources above. How we work
By
Nakoda News Desk
Nakoda News covers AI and business. Every story links the sources it draws on; how we work is set out in our editorial standards.
Related coverage
- Research
Tether Releases BotPsy, a 0.8-Billion-Parameter Agent Model Built to Run on Devices
22 hours ago · 2 min read
Research Meta Researchers Release e-means, a Faster Replacement for k-means Clustering in FAISS
1 day ago · 1 min read
- Research
UAE's First Radar Satellite Sirb-1 Clears Final Design Review, Targets 2028 Launch
1 day ago · 2 min read
- Research
Startup PSI Uses Anthropic Model to Prove a Long-Open Quantum Computing Conjecture
1 day ago · 2 min read
- Research
Nvidia Unveils GR00T 2, a Robot Model That Learns New Tasks From Human Video
1 day ago · 3 min read