MBZUAI's IFM Releases PAN 2, an Open World Model That Simulates Actions as Video
The Abu Dhabi lab is publishing weights and full training code for the 29-billion-parameter model, which leads its own planning tests but still fails most long plans.
By Nakoda News Desk
·3 min read
Prefer Nakoda News on Google
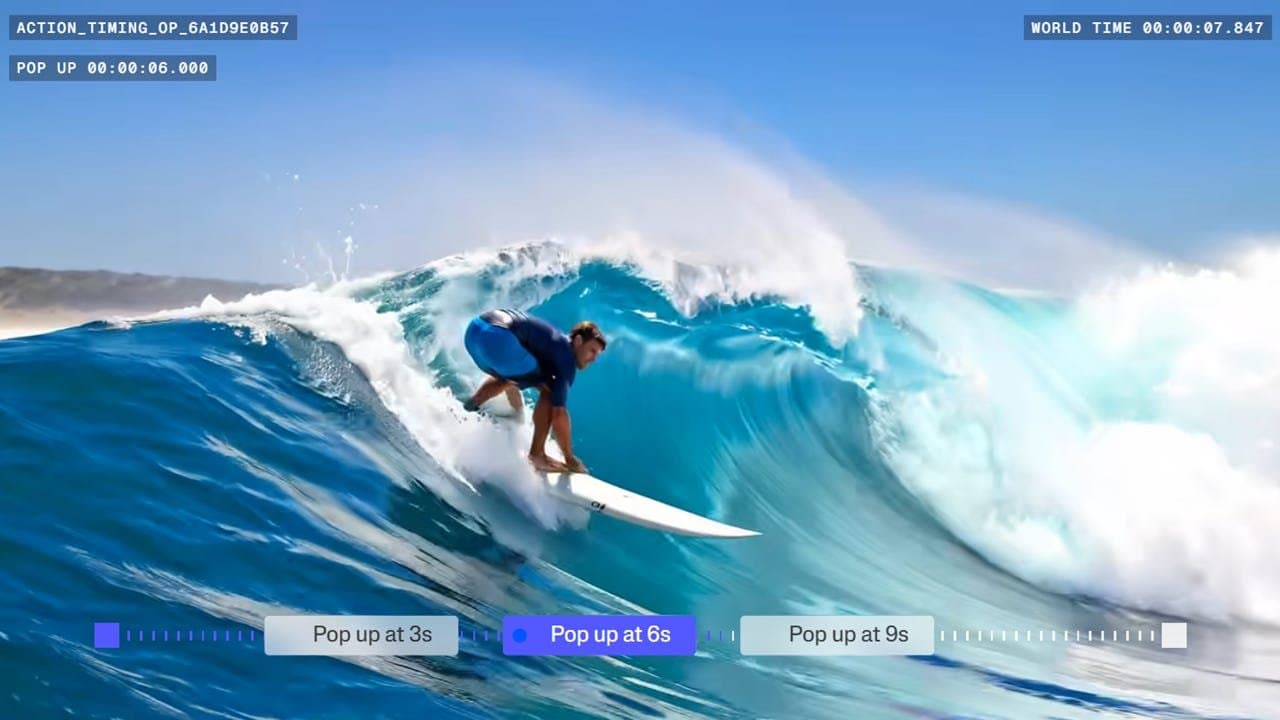
The Institute of Foundation Models, the research lab of Abu Dhabi's Mohamed bin Zayed University of Artificial Intelligence, has released PAN 2, a world model that takes a starting scene and a written action and generates video showing what happens next. IFM is publishing the model's weights, training code and inference code under the Apache 2.0 licence.
World models are meant to let robots and software agents rehearse an action in simulation before trying it in the real world, where mistakes can be slow, costly or impossible to undo. IFM calls the approach simulative reasoning: an agent proposes several plans, the world model plays each one out, and the agent acts on the best. Few groups building such systems release full training code alongside the weights, so outside researchers can rebuild and adapt PAN 2 rather than only run it.
The release, announced on X on November 10, succeeds the first PAN model, which IFM published in November 2025.
A Language Model Writes the Script
PAN 2 splits the work into two stages. A large language model first reads the scene and the requested actions and writes the next state of the world as a structured, time-stamped description of events, actions tied to specific actors, and camera movement. IFM says any instruction-following language model can fill that role; its technical report uses Kimi K3 by default. A 29-billion-parameter diffusion transformer, which IFM trained from scratch on hundreds of millions of annotated videos chosen for physical dynamics rather than visual appeal, then turns that description into video.
According to the model card, a frozen Qwen3.5-9B text encoder conditions the diffusion model and a Wan 2.2 decoder renders the frames, at 704 by 1,248 pixels and 24 frames per second, for clips of up to 20 seconds. The design follows the Generative Latent Prediction architecture developed by IFM founder Eric Xing and the institute's researchers, which predicts change in an internal representation and then reconstructs what would be observed.
IFM's own tests suggest the language-model stage carries much of the load. Without it, the share of multi-step plans the system completed fell from 34.0% to zero, and step completion dropped from 75.1% to 8.7%.
Where It Trails MiniMax-H3
On IFM's self-reported results, PAN 2 completed more full plans than any of the six models tested on 100 everyday multi-step tasks. Even so, at 34.0%, about two in three simulated plans missed at least one step. Across six core capabilities, including physical consistency, causal coherence and whether objects persist, PAN 2 placed just behind MiniMax-H3 and ahead of four other models. MiniMax-H3 also led on single actions and in human preference tests, and scored 42.91 to PAN 2's 37.48 on the Physics-IQ benchmark under default settings. IFM says PAN 2 ranks third overall on the Physics-IQ Verified leaderboard and first among open-weight models.
The model card lists further limits. Results are sensitive to prompt wording, appearance drifts across clips in long interactions, text describes fine-grained manipulation only coarsely, and the model can skip physical constraints mid-simulation. It is also demanding to run: each generation worker holds the full 29-billion-parameter model, which means one data-centre GPU per worker. IFM says long-term world consistency remains unsolved.
PAN 2 is MBZUAI's second world-model release in weeks. In October the university unveiled WorldGuide, a video world model for procedural tasks such as folding origami, assembling furniture or cooking, which it said reached 33.33% task success on its own benchmark against 29.90% for MiniMax-H3. IFM has named robotics and education as possible early uses, and the PAN 2 weights are available now on Hugging Face.
Sources
- Middle East AI News · MBZUAI’s IFM opens PAN 2 world model to all
- MarkTechPost · MBZUAI’s IFM Releases PAN 2, an Open 29B World Model for Physical AI
- Hugging Face · IFM/PAN2 model card
Produced with AI assistance from the sources above. How we work
By
Nakoda News Desk
Nakoda News covers AI and business. Every story links the sources it draws on; how we work is set out in our editorial standards.
Related coverage
- Research
Startup PSI Uses Anthropic Model to Prove a Long-Open Quantum Computing Conjecture
15 hours ago · 2 min read
- Research
Nvidia Unveils GR00T 2, a Robot Model That Learns New Tasks From Human Video
16 hours ago · 3 min read
- Research
Anthropic's Fable 5.2 Completes 41% of Real Freelance Jobs on Remote Labor Index
19 hours ago · 2 min read
Research Insilico Medicine Open-Sources Longevity Grok, a Health AI That Scores Its Own Predictions
21 hours ago · 2 min read
- Research
Google DeepMind Uses AI Tool to Formally Verify Key Guarantees of the Signal Protocol
1 day ago · 2 min read