Amazon Researchers Release HOPE, a Method for Cutting Unused Experts From MoE Models
The open-source technique accounts for how experts work together when deciding which to delete, and kept a halved Qwen model's coding score on par with the original.
By Nakoda News Desk
·2 min read
Prefer Nakoda News on Google
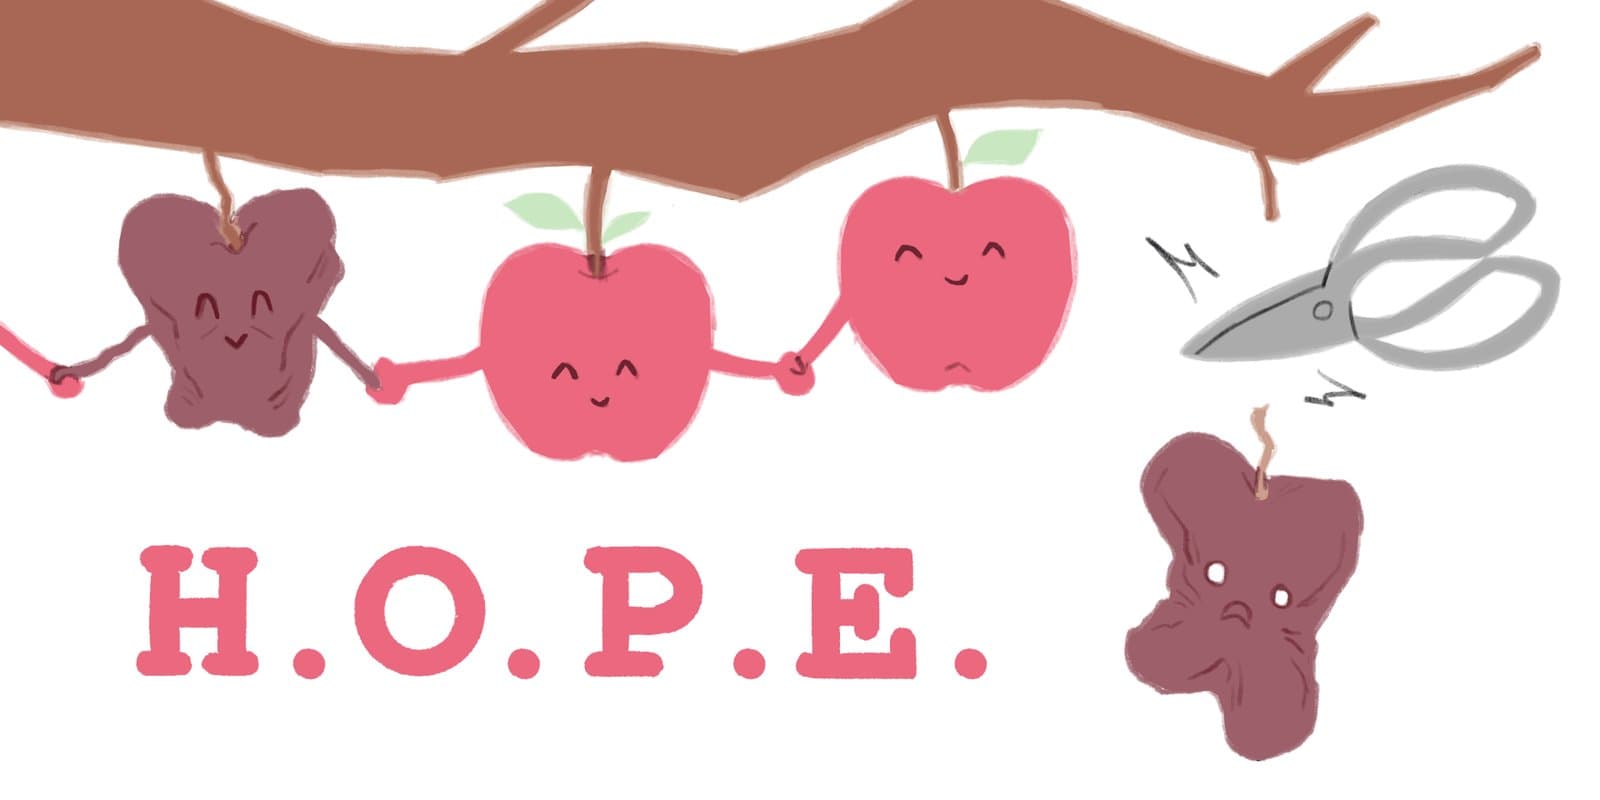
Amazon researchers have released HOPE, short for Higher-Order Pruning of Experts, an open-source method for shrinking mixture-of-experts language models by permanently deleting the experts that matter least. The team says it beats existing pruning methods most clearly when half the experts are removed.
Mixture-of-experts (MoE) designs let model builders scale to hundreds of billions of parameters, but every expert must sit in memory at inference time even though few are used for any one token. In a blog post, the researchers wrote that Qwen3.5-122B has 256 experts in each of its 48 MoE layers and uses only 8 per layer for a given token. They said expert networks account for about 95% of the model's roughly 250 GB parameter footprint. Pruning cuts that memory without retraining, avoids the latency of swapping experts on and off a device, and can be combined with quantization. For companies running large open models on their own hardware, that means cheaper deployment.
The hard part is deciding which experts can go. Existing methods give each expert an independent importance score and delete the lowest scorers. The Amazon team argues that experts form stable cooperative groups that tend to fire together, so removing one can break a group even when its own score looks low. HOPE adds pairwise interaction terms between experts and selects which ones to cut by solving a quadratic optimisation problem.
The researchers tested HOPE on Qwen3.5-122B, Qwen3.5-35B and GLM-4.5-Air at pruning rates from 10% to 50%. They compared it with four existing methods: REAP, MAN, EAN and frequency-based pruning. Across all conditions HOPE had the best average rank, 2.07 out of five methods. At 50% pruning its average rank was 1.58, against 2.42 for REAP, the next best.
The biggest gains came on agentic coding, up to 6.1% above the next-best method on SWE-Bench Pro. On Qwen3.5-35B with half its experts removed, HOPE scored 42.3 on that benchmark, compared with 41.8 for the unpruned model, while REAP fell to 36.2.
HOPE needs the same single calibration pass as other expert-pruning methods. The researchers said the extra optimisation step takes about one to two seconds per layer, though another part of the post puts it at a few seconds. The blog post gives no measured memory savings for the pruned models, and it does not say whether pruned checkpoints will be published.
The paper, "Higher-Order Pruning of Experts in Mixture-of-Experts Language Models", is by Alex M. Tseng, Prannay Kaul, Luca Zancato, Wei Xia and Stefano Soatto. The code is available in Amazon's awslabs/HOPE repository on GitHub.
Sources
- Hugging Face · Your Experts Have Partners. There's HOPE for Keeping Them Together
Produced with AI assistance from the sources above. How we work
By
Nakoda News Desk
Nakoda News covers AI and business. Every story links the sources it draws on; how we work is set out in our editorial standards.
Related coverage
Research GSMA Forecasts MENA Mobile Economy at $470 Billion by 2030 as MWC Doha Opens
13 hours ago · 2 min read
Research Toshiba Europe Wins UK Contract to Build Quantum Network Technology With BT and Colt
15 hours ago · 1 min read
- Research
UAE and Saudi Firms Plan to Outspend Global Average on Digital Transformation, GSMA Finds
15 hours ago · 2 min read
- Research
Battery Backups Checking Their Charge in Sync Cause Minute-by-Minute Grid Dips, Study Finds
1 day ago · 3 min read
Research Open-Source Llama-Modchip Runs 284B-Parameter DeepSeek Model on a 64GB PC Without a GPU
1 day ago · 2 min read